

Send a first decision
This run triages a support ticket with one question of each type.triage.json
POST /v1/runs is synchronous. It returns 200 once the run has settled, with the answers in the body:
billing queue (0.71), and the customer sits between annoyed and furious (1.34 on a 0-indexed scale). The run cost 19 micro-USD.
Request fields
SendContent-Type: application/json and an Idempotency-Key header of 1 to 255 bytes of visible text. Your API key needs the runs_write scope. Unknown fields are refused with 400 invalid_body.
Verdict fields are refused on a decision run, with a message that names the field to use instead:
Question shapes
Each question is an object tagged bytype. Unknown keys are refused.
Every type also accepts three optional fields:
depends_on: question ids that must be read in an earlier stage.ask_if: maps a question id to the answer names that trigger this question. When the condition fails, the answer isskipped.alone:truereads this question on its own rather than jointly with the rest of its stage.
depends_on, ask_if and alone in full.
Question set limits
A question set that breaks one of these is refused with400 invalid_decision_questions before anything is charged. The message starts with the decision questions are not acceptable: followed by the reason.
The whole request body is capped at 4 MiB (
413 body_too_large).
The response
A completed decision run returns the run fields plus adecision object.
Stored copies of a run are thinner than the live response.
GET /v1/runs/{run_id} and a replayed Idempotency-Key return the answers, usage and cost_micros, but no cost_basis, and the decision has no model, stages, thought_tokens or thought_closed. The stream carries the stored answers only, without usage or cost. Save what you need from the first response.Answer shapes
Any answered question can also carry:
label_mass: the total probability the model put on your legal labels before the probabilities were renormalised over them.answered_within_labels: whether the single most likely token was one of your labels. When it isfalse, the probabilities are a renormalisation over labels the model did not favour. Treat that answer with suspicion, whatever its numbers say.
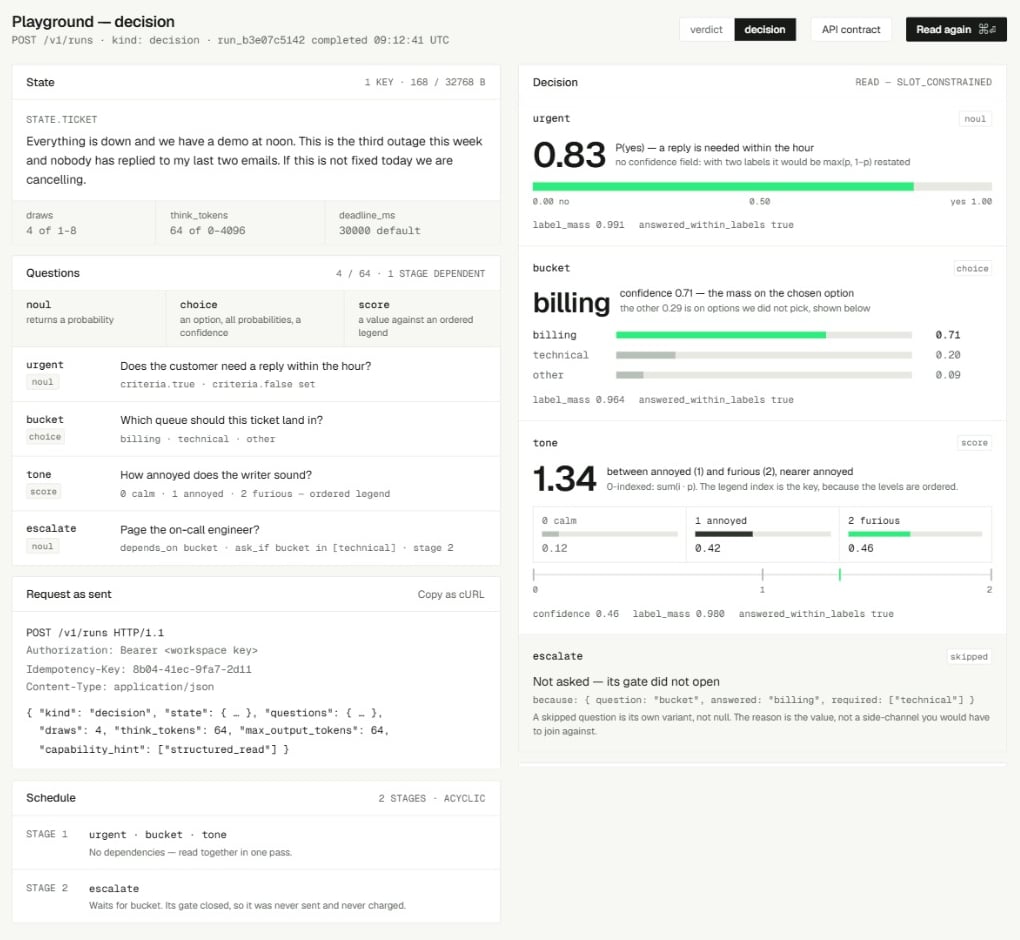
Stages
Questions are scheduled into stages by their dependencies. A stage holds every question whosedepends_on questions are all in earlier stages. Within a stage, questions follow question_order, or sorted ids when you leave it out.
A set with no depends_on runs in one stage, as in the example above: "stages": [["urgent", "bucket", "tone"]]. Whatever the number of stages, a decision is exactly one model call.
Costs
Neon 1.1 costs 0.042 per million output tokens (42,000 micro-USD per million). Input and output are each rounded up to a whole micro-USD, then added:- A run may never cost more than 20,000 micro-USD ($0.02). That whole ceiling is held from your balance while the run is in flight, and the run is charged its real cost when it settles.
cost_basisisestimatedwhendrawsis greater than 1, or when usage was not reported. The cost is then the pre-call estimate at Neon 1.1 prices.- A replayed
Idempotency-Keyis never charged again. - Every refusal before the model call,
400,402,409,413at admission and429, costs nothing.
Tips
Keep labels short and single-token-friendly
Neon 1.1 reads a probability off each label. Admission does not check whether every option name and level name works as a single token, or whether the set fits the answer template. When one does not, the run fails late with503 decision_unavailable. Change the labels rather than retrying the same question set.
- Use short, common, single words:
billing,other,calm,furious. - Avoid multi-word names, punctuation, numbers and rare words as labels.
- Put the explanation in the
choicedescription or thenoulcriteria, not in the label.
Stay under 262,144 input tokens
Neon 1.1 reads at most 262,144 input tokens (256k) per decision. The input estimate is roughly a quarter of the byte length of thestate, plus a quarter of the byte length of instructions and questions. A run above the limit is refused with 413 input_too_large.
Idempotency-Key.
Set a client timeout above the deadline
deadline_ms defaults to 30 seconds plus 120 seconds per 262,144 input tokens (about 90 seconds for 128k tokens), and never exceeds 150 seconds. Give your HTTP client a timeout of at least 160 seconds, longer than any deadline, so the server, not your client, decides when the run is over. A run that runs out of time returns 504 deadline_exceeded.
What goes wrong
After a
503 or 504, retry with a new Idempotency-Key. A run that failed before the model answered is not rerun under the same key: a replay only returns 202 with the stored pending run. The idempotency and error handling guides cover the full rules.
Related
- Decision questions - the concepts behind question types, stages and answers.
- invalid_decision_questions - every reason a question set is refused.
- Limits - every per-request limit in one table.
- Idempotency - when to reuse an
Idempotency-Keyand when to mint a new one. - Model Router - use Neon 1.1 to pick a model for any prompt.