> ## Documentation Index
> Fetch the complete documentation index at: https://docs.opentype.dev/llms.txt
> Use this file to discover all available pages before exploring further.
# Decision runs
> Send a JSON state and typed questions to Neon 1.1 and get a probability for every answer: request fields, response, stages, costs and limits.
A decision run asks Neon 1.1 a set of typed questions about one piece of state, a support ticket, a message or a database row, and returns a probability for every answer you defined. This guide is for developers building the request by hand: it covers every field, the response, how questions are grouped into stages, what a run costs, and what goes wrong.
For the three question types in depth, see [noul](/guides/noul-questions), [choice](/guides/choice-questions) and [score](/guides/score-questions) questions. For gating one question on another, see [conditional questions](/guides/conditional-questions).
## Send a first decision
This run triages a support ticket with one question of each type.
```json triage.json theme={"system"}
{
"kind": "decision",
"model": "neon-1.1",
"instructions": "You triage customer support tickets.",
"state": {"ticket": "I was charged twice this month and nobody answers my emails.", "plan": "pro"},
"questions": {
"urgent": {"type": "noul", "instructions": "reply within the hour?"},
"bucket": {"type": "choice", "instructions": "which queue?",
"criteria": {"billing": "payment problems", "other": null}},
"tone": {"type": "score", "instructions": "how annoyed?",
"criteria": ["calm", "annoyed", "furious"]}
},
"question_order": ["urgent", "bucket", "tone"],
"think_tokens": 64,
"max_output_tokens": 16
}
```
```bash curl theme={"system"}
curl -sS https://api.opentype.dev/v1/runs \
-H "Authorization: Bearer $OPENTYPE_API_KEY" \
-H "Content-Type: application/json" \
-H "Idempotency-Key: ticket-4822-triage" \
-d @triage.json
```
```ts TypeScript theme={"system"}
import { readFileSync } from "node:fs";
const res = await fetch("https://api.opentype.dev/v1/runs", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.OPENTYPE_API_KEY}`,
"Content-Type": "application/json",
// Derive the key from the work item, so a retry of the same ticket is never run twice.
"Idempotency-Key": "ticket-4822-triage",
},
body: readFileSync("triage.json", "utf8"),
});
const run = await res.json();
if (!res.ok) {
throw new Error(`${res.status} ${run.error.code} (${run.error.request_id})`);
}
console.log(run.decision.answers.urgent.probability); // 0.83
```
```python Python theme={"system"}
import os
import requests
with open("triage.json") as f:
body = f.read()
res = requests.post(
"https://api.opentype.dev/v1/runs",
headers={
"Authorization": f"Bearer {os.environ['OPENTYPE_API_KEY']}",
"Content-Type": "application/json",
# Derive the key from the work item, so a retry of the same ticket is never run twice.
"Idempotency-Key": "ticket-4822-triage",
},
data=body,
timeout=160, # longer than the largest deadline (150 s)
)
run = res.json()
if not res.ok:
raise RuntimeError(f"{res.status_code} {run['error']['code']} ({run['error']['request_id']})")
print(run["decision"]["answers"]["urgent"]["probability"]) # 0.83
```
`POST /v1/runs` is synchronous. It returns `200` once the run has settled, with the answers in the body:
```json theme={"system"}
{
"run_id": "run_a4314b6cc08f4bd8814099a613abeb44",
"kind": "decision",
"state": "completed",
"input_digest": "2e7d2c03a9507ae265ecf5b5356885a53393a2029d241394997265a1a25aefc6",
"output_digest": "18ac3e7343f016890c510e93f935261169d9e3f565436429830faf0934f4f8e4",
"decision": {
"answers": {
"bucket": {"answered_within_labels": true, "choice": "billing", "confidence": 0.71,
"label_mass": 0.964, "probabilities": {"billing": 0.71, "other": 0.29}, "type": "choice"},
"tone": {"answered_within_labels": true, "confidence": 0.46, "label_mass": 0.98,
"legend": {"0": "calm", "1": "annoyed", "2": "furious"},
"probabilities": {"0": 0.12, "1": 0.42, "2": 0.46}, "score": 1.34, "type": "score"},
"urgent": {"answered_within_labels": true, "label_mass": 0.991, "probability": 0.83, "type": "noul"}
},
"draws": 1,
"model": "neon-1.1",
"read": "slot_constrained",
"stages": [["urgent", "bucket", "tone"]],
"thought_tokens": 48,
"thought_closed": true
},
"usage": {"input_tokens": 412, "output_tokens": 23},
"cost_micros": 19,
"cost_basis": "provider_reported",
"replayed": false
}
```
Read it as: the ticket is probably urgent (P(yes) 0.83), belongs in the `billing` queue (0.71), and the customer sits between annoyed and furious (1.34 on a 0-indexed scale). The run cost 19 micro-USD.
## Request fields
Send `Content-Type: application/json` and an `Idempotency-Key` header of 1 to 255 bytes of visible text. Your API key needs the `runs_write` scope. Unknown fields are refused with `400 invalid_body`.
| Field | Type | Required | Default | Rules |
| ------------------- | ---------------- | ------------------- | -------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `kind` | string | yes, for a decision | `"verdict"` | Send `"decision"`. Leaving it out makes the run a [verdict run](/guides/verdict-runs). |
| `state` | any JSON value | yes | | The thing being judged. A string is sent as is; an object, array, number or boolean is sent as its JSON text. |
| `questions` | object | yes | | Maps a question id to a question. 1 to 64 questions. See [Question shapes](#question-shapes). |
| `instructions` | string | no | none | Context that applies to every question, such as the role the reader plays. |
| `question_order` | array of strings | no | ids in sorted order | The order questions are read within a stage. Must name exactly the keys of `questions`, no more and no fewer. |
| `draws` | integer | no | `1` | 1 to 8. With more than 1, `cost_micros` is an estimate (see [Costs](#costs)). |
| `think_tokens` | integer | no | `0` | 0 to 4,096. Lets the model think before it answers. The thought text is never returned. |
| `max_output_tokens` | integer | **yes** | | Must be greater than 0. |
| `deadline_ms` | integer | no | 30,000 plus 120,000 per 262,144 input tokens | Clamped to 1 to 150,000: `0` becomes `1`, and anything above 150,000 becomes 150,000. |
| `model` | string | no | none | `neon-1.1` or `neon-latest`; `neon-latest` resolves to Neon 1.1. Any other value is refused with `400 unknown_model`. |
| `capability_hint` | array of strings | no | `[]` | Values from `chat`, `reasoning`, `tools`, `vision`, `streaming`, `embedding`, `structured_read`; at most 7, no duplicates. Can only narrow routing, never widen it. Mistakes are refused with `400 invalid_verdict_schema`. |
Verdict fields are refused on a decision run, with a message that names the field to use instead:
| You sent | `400 invalid_body` message ends with |
| ---------- | --------------------------------------------------------- |
| `system` | `system is only valid on a verdict run; use instructions` |
| `messages` | `messages is only valid on a verdict run; use state` |
| `schema` | `schema is only valid on a verdict run; use questions` |
## Question shapes
Each question is an object tagged by `type`. Unknown keys are refused.
| `type` | Shape | Answer names |
| -------- | -------------------------------------------------------------------------------------------- | ----------------- |
| `noul` | `{"type": "noul", "instructions": string, "criteria"?: {"true"?: string, "false"?: string}}` | `yes`, `no` |
| `choice` | `{"type": "choice", "instructions": string, "criteria": {option_name: description or null}}` | your option names |
| `score` | `{"type": "score", "instructions": string, "criteria": [level names, in order]}` | your level names |
Every type also accepts three optional fields:
* `depends_on`: question ids that must be read in an earlier stage.
* `ask_if`: maps a question id to the answer names that trigger this question. When the condition fails, the answer is `skipped`.
* `alone`: `true` reads this question on its own rather than jointly with the rest of its stage.
The [conditional questions](/guides/conditional-questions) guide covers `depends_on`, `ask_if` and `alone` in full.
### Question set limits
A question set that breaks one of these is refused with `400 invalid_decision_questions` before anything is charged. The message starts with `the decision questions are not acceptable: ` followed by the reason.
| Limit | Value | Reason in the message |
| ------------------------- | ---------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| Questions per run | 1 to 64 | `a decision needs at least one question`, `the decision asks more questions than permitted` |
| Question id | non-empty, no `:`, no newline | `every question id must be non-empty and contain no ':' or newline` |
| Question ids | unique | `two questions share an id` |
| Alternatives per question | 2 to 20 (a `noul` always has 2) | `every question needs at least two and at most twenty alternatives` |
| Alternative names | unique within a question | `two alternatives of one question share a name` |
| References | every `depends_on` entry and `ask_if` key names another question in the set | `a question depends on a question that is not another question in this set` |
| Cycles | none | `the questions depend on each other in a cycle` |
| `ask_if` values | non-empty, and answers the target can produce | `an ask_if names no answers, so it can never be satisfied`, `an ask_if names an answer the question it depends on cannot produce` |
| `draws` | 1 to 8 | `draws must be at least one and at most eight` |
| `think_tokens` | 0 to 4,096 | `think_tokens must be at most four thousand and ninety-six` |
| Contract size | `instructions` + `questions` + `draws` + `think_tokens`, at most 32 KiB. The `state` does not count. | `the question set is larger than the permitted size` |
The whole request body is capped at 4 MiB (`413 body_too_large`).
## The response
A completed decision run returns the run fields plus a `decision` object.
| Field | Meaning |
| ---------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `run_id` | `run_` followed by 32 hex characters. Use it to [read the run again](/guides/polling). |
| `state` | `completed` on a fresh run. A replayed key can also return `failed` with `200`, for a run that failed after the model answered. |
| `input_digest`, `output_digest` | SHA-256 hex digests of what was read and what was answered. |
| `decision.answers` | One answer per question id, keys in sorted order. |
| `decision.draws` | The number of draws used. |
| `decision.model` | `neon-1.1`. |
| `decision.read` | `slot_constrained`. |
| `decision.stages` | The schedule that ran, as an array of arrays of question ids. |
| `decision.thought_tokens`, `decision.thought_closed` | Present when the model thought before answering. |
| `usage` | `input_tokens` and `output_tokens`. |
| `cost_micros` | What the run cost, in micro-USD (1,000,000 = \$1). |
| `cost_basis` | `provider_reported` or `estimated`. |
| `replayed` | `true` when the body came from storage rather than a fresh run. |
Stored copies of a run are thinner than the live response. `GET /v1/runs/{run_id}` and a replayed `Idempotency-Key` return the answers, `usage` and `cost_micros`, but no `cost_basis`, and the decision has no `model`, `stages`, `thought_tokens` or `thought_closed`. The stream carries the stored answers only, without `usage` or cost. Save what you need from the first response.
### Answer shapes
| Answer `type` | Fields |
| ------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `noul` | `probability`: P(yes). There is no `confidence`. |
| `choice` | `choice` (the most likely option), `probabilities` keyed by option name, `confidence` |
| `score` | `score` (the expected level, 0-indexed), `legend` mapping index to level name, `probabilities` keyed by index string, `confidence` |
| `skipped` | `because`: `{question, answered?, required}`. The `ask_if` condition was not met. |
Any answered question can also carry:
* `label_mass`: the total probability the model put on your legal labels before the probabilities were renormalised over them.
* `answered_within_labels`: whether the single most likely token was one of your labels. When it is `false`, the probabilities are a renormalisation over labels the model did not favour. Treat that answer with suspicion, whatever its numbers say.
Every probability and confidence is a finite number from 0 to 1.
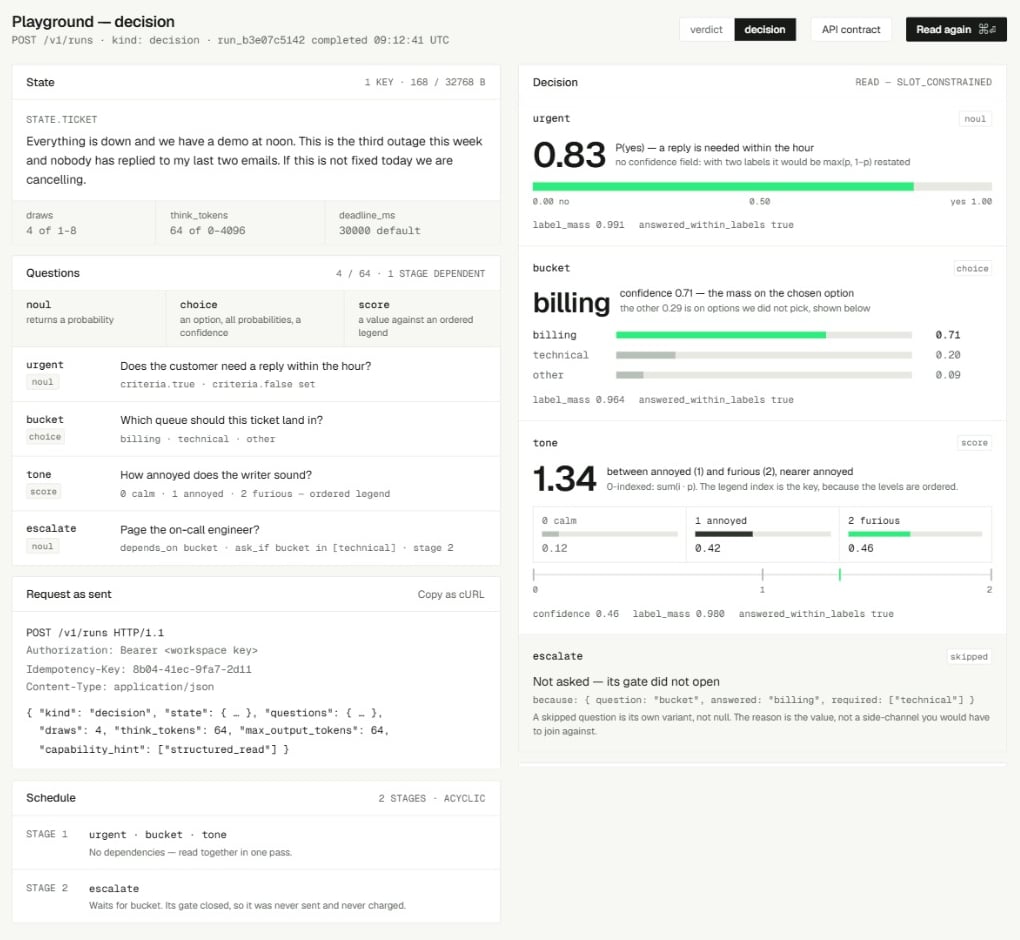 ## Stages
Questions are scheduled into stages by their dependencies. A stage holds every question whose `depends_on` questions are all in earlier stages. Within a stage, questions follow `question_order`, or sorted ids when you leave it out.
A set with no `depends_on` runs in one stage, as in the example above: `"stages": [["urgent", "bucket", "tone"]]`. Whatever the number of stages, a decision is exactly one model call.
## Costs
Neon 1.1 costs $0.042 per million input tokens and $0.042 per million output tokens (42,000 micro-USD per million). Input and output are each rounded up to a whole micro-USD, then added:
```text theme={"system"}
input ceil(42,000 × 412 / 1,000,000) = 18
output ceil(42,000 × 23 / 1,000,000) = 1
cost_micros = 19
```
* A run may never cost more than 20,000 micro-USD (\$0.02). That whole ceiling is held from your balance while the run is in flight, and the run is charged its real cost when it settles.
* `cost_basis` is `estimated` when `draws` is greater than 1, or when usage was not reported. The cost is then the pre-call estimate at Neon 1.1 prices.
* A replayed `Idempotency-Key` is never charged again.
* Every refusal before the model call, `400`, `402`, `409`, `413` at admission and `429`, costs nothing.
The full price and credit rules are on [Models and pricing](/getting-started/models-and-pricing) and [Credits and billing](/guides/credits-and-billing).
## Tips
### Keep labels short and single-token-friendly
Neon 1.1 reads a probability off each label. Admission does not check whether every option name and level name works as a single token, or whether the set fits the answer template. When one does not, the run fails late with `503 decision_unavailable`. Change the labels rather than retrying the same question set.
* Use short, common, single words: `billing`, `other`, `calm`, `furious`.
* Avoid multi-word names, punctuation, numbers and rare words as labels.
* Put the explanation in the `choice` description or the `noul` `criteria`, not in the label.
### Stay under 262,144 input tokens
Neon 1.1 reads at most 262,144 input tokens (256k) per decision. The input estimate is roughly a quarter of the byte length of the `state`, plus a quarter of the byte length of `instructions` and `questions`. A run above the limit is refused with `413 input_too_large`.
```python theme={"system"}
import json, math
def input_estimate(body: dict) -> int:
"""Rough client-side estimate, before you send."""
state = body["state"]
prompt = state if isinstance(state, str) else json.dumps(state, separators=(",", ":"))
contract = json.dumps(
{k: body.get(k) for k in ("instructions", "questions", "draws", "think_tokens")},
separators=(",", ":"),
)
return math.ceil(len(prompt.encode()) / 4) + math.ceil(len(contract.encode()) / 4)
assert input_estimate(json.load(open("triage.json"))) <= 262_144
```
A long state is accepted, but it costs more and takes longer. Trim it to the fields the questions actually need. Because the body changes when you trim, send it with a new `Idempotency-Key`.
### Set a client timeout above the deadline
`deadline_ms` defaults to 30 seconds plus 120 seconds per 262,144 input tokens (about 90 seconds for 128k tokens), and never exceeds 150 seconds. Give your HTTP client a timeout of at least 160 seconds, longer than any deadline, so the server, not your client, decides when the run is over. A run that runs out of time returns `504 deadline_exceeded`.
## What goes wrong
| Status | Code | Cause | Fix |
| ------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------- |
| `400` | [`invalid_body`](/problems/invalid_body) | A verdict field, an unknown field, a missing `state` or `questions`, `max_output_tokens` of 0, or a `question_order` that does not match the keys | Fix the body. The same key may be reused. |
| `400` | [`invalid_decision_questions`](/problems/invalid_decision_questions) | The question set breaks a [limit](#question-set-limits) | Fix the questions. Nothing was charged. |
| `400` | [`unknown_model`](/problems/unknown_model) | `model` is not `neon-1.1` or `neon-latest` | Send a supported id, or leave `model` out. |
| `400` | [`idempotency_key_required`](/problems/idempotency_key_required) | No `Idempotency-Key` header | Send one per logical request. |
| `402` | [`insufficient_credits`](/problems/insufficient_credits) | The balance cannot cover the run's hold | [Add credit](/guides/handling-insufficient-credits), then retry with the same key. |
| `409` | [`idempotency_conflict`](/problems/idempotency_conflict) | The key was already used with a different body | Use a new key for a new body. |
| `413` | [`input_too_large`](/problems/input_too_large) | The input estimate is above 262,144 tokens | Shrink the `state` or the questions, then retry with a new `Idempotency-Key`. |
| `429` | [`organization_spend_quota_exhausted`](/problems/organization_spend_quota_exhausted), [`organization_token_quota_exhausted`](/problems/organization_token_quota_exhausted) | The period quota is used up | See [Spend limits and quotas](/guides/spend-limits-and-quotas). |
| `503` | [`decision_unavailable`](/problems/decision_unavailable) | No route could serve the decision, or the question set was refused at read time | Check the [labels](#keep-labels-short-and-single-token-friendly). Otherwise retry later with a new key. |
| `504` | [`deadline_exceeded`](/problems/deadline_exceeded) | The deadline passed | Raise `deadline_ms` or shrink the input, then retry with a new key. |
After a `503` or `504`, retry with a **new** `Idempotency-Key`. A run that failed before the model answered is not rerun under the same key: a replay only returns `202` with the stored `pending` run. The [idempotency](/guides/idempotency) and [error handling](/guides/error-handling) guides cover the full rules.
## Related
* [Decision questions](/getting-started/decision-questions) - the concepts behind question types, stages and answers.
* [invalid\_decision\_questions](/problems/invalid_decision_questions) - every reason a question set is refused.
* [Limits](/reference/limits) - every per-request limit in one table.
* [Idempotency](/guides/idempotency) - when to reuse an `Idempotency-Key` and when to mint a new one.
* [Model Router](/guides/model-router) - use Neon 1.1 to pick a model for any prompt.