> ## Documentation Index
> Fetch the complete documentation index at: https://docs.opentype.dev/llms.txt
> Use this file to discover all available pages before exploring further.
# Playground
> Run a decision read by hand in the console: write a state and typed questions, read each answer and its cost, then copy the request as cURL.
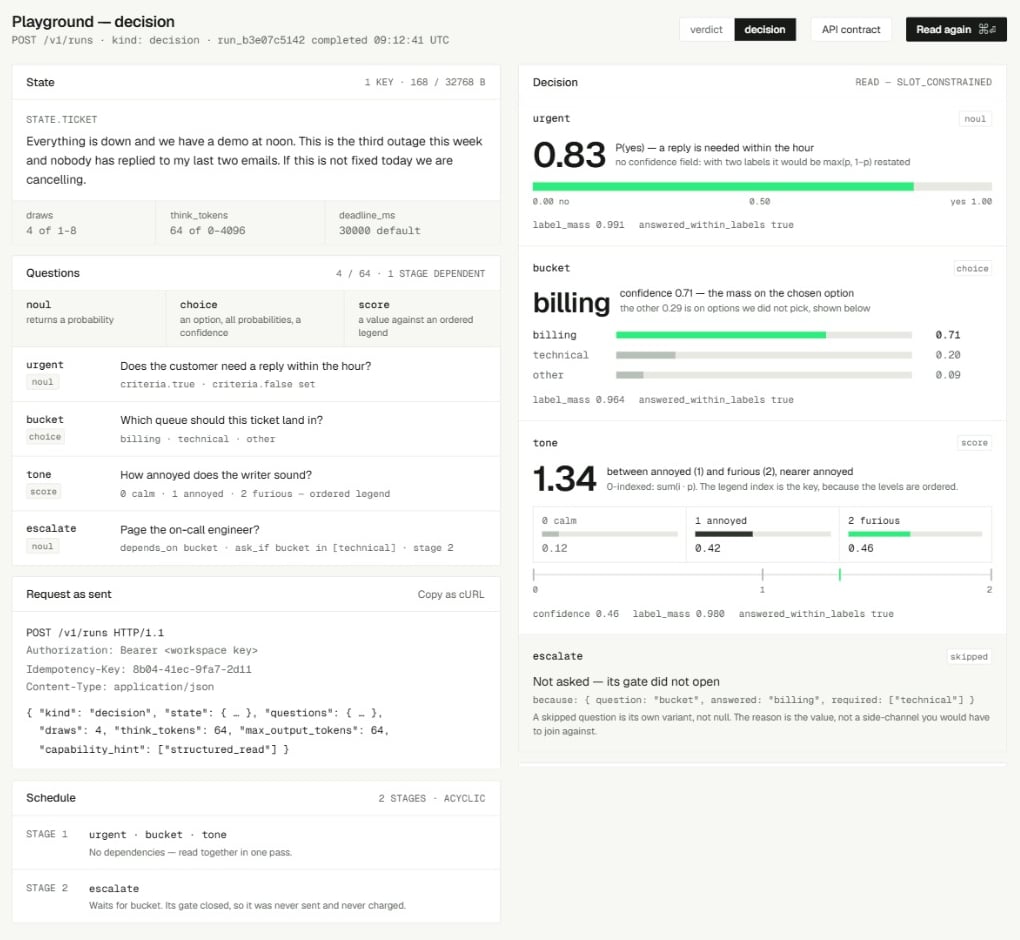
The Playground is the console page where you try a decision run by hand, before you write any code. You paste a state, write a few typed questions, press **Run**, and read every answer with the probabilities behind it and what the read cost. Use it to shape your questions and labels, then copy the exact request into your own code.
Open it at [console.opentype.dev/playground](https://console.opentype.dev/playground). It is also where the console opens after sign-in.
A Playground read is a real run. It goes to `POST /v1/runs` on `https://api.opentype.dev` as you, is answered by Neon 1.1, is charged to your organization's balance, and appears on [Usage](/console/usage). It needs the `runs_write` scope, which owners, admins and members hold.
 ## The page at a glance
The header reads **Playground**, with a status line under it: `POST /v1/runs · kind decision ·` followed by one of these.
| Status | Meaning |
| ------------------------------ | ---------------------------------------------------------- |
| `nothing read in this tab yet` | You have not run anything since the page opened |
| `reading` | A read is in flight |
| `run_… answered` | The last read answered; the start of its `run_id` is shown |
| `refused · {code}` | The last read was refused, with its error code |
Three buttons sit on the right:
* **Clear** empties both editors and resets the answer panel.
* **Share** copies a link that reopens the Playground with your state and questions. It reads **Link copied** for a moment.
* **Run** sends the read. Press ⌘+Enter (or Ctrl+Enter) from anywhere on the page. **Run** is disabled while the editors have issues and while a read is in flight; it reads **Reading** then.
The left column holds **State**, **Questions** and **Request as sent**. The right column holds **Decision**, **This read** once a read has answered, and **Example requests**.
## Write the state
**State** is the thing you want read: a support ticket, an email, a contract clause, a row of data.
* Text is sent as is, as a JSON string.
* Text that parses as a JSON object, such as `{"ticket": "…", "plan": "pro"}`, is sent as an object. **Format** appears and pretty-prints it.
* The panel's meta shows what will be sent and its size: `text · 212 / 32,768 B`, or `json · 3 keys · 140 / 32,768 B`.
The console refuses a state over 32,768 bytes before it sends anything. A state that fits that limit can still be too long for the model; the API then refuses it with `413 input_too_large`. See [input\_too\_large](/problems/input_too_large).
## Write the questions
**Questions** holds up to 64 questions, and its meta counts them: `4 / 64 · ready`, or `4 / 64 · 2 issues`. Add one with the three buttons at the top of the panel.
| Button | What it asks | What comes back |
| ------------ | -------------------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
| **+ noul** | A yes/no question. Returns a probability, not a word. | `probability`: P(yes), between 0 and 1 |
| **+ choice** | 2-20 named options. Returns one, every option's mass, a confidence. | `choice`, `probabilities` keyed by option name, `confidence` |
| **+ score** | An ordered legend of 2-9 levels. Returns a value between its levels. | `score` between the first level (0) and the last, `probabilities` per level, `confidence` |
Each new question arrives filled with a starter you then edit: `is_true` for noul, `pick` for choice, `rate` for score. A second question of the same type gets `_2`, then `_3`, appended to its id.
Each question row has four parts:
* **Id**: the key the answer comes back under.
* **Type**: `noul`, `choice` or `score`. You can change it in place.
* **The question, in one line**: the instruction the model reads.
* **Labels**: for a noul, the fixed text `yes · no — returns P(yes)`. For a choice, the options as a comma-separated list (`option, option, …`). For a score, the levels in order from lowest to highest (`lowest, …, highest`).
Remove a question with **×** at the end of its row.
### Limits the editor checks
The Playground checks everything below as you type, lists up to six issues under the questions as `field — reason`, and keeps **Run** disabled until they are fixed.
| What | Limit | Message |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------ | -------------------------------------------------------------------- |
| State | Not empty, at most 32,768 bytes | `state is empty`, `state is 40210 B, the limit is 32768 B` |
| Questions | 1 to 64 | `at least one question is required`, `65 questions, the limit is 64` |
| Id | Matches `^[a-z][a-z0-9_]{0,31}$`: starts with a lowercase letter, then lowercase letters, digits or `_`, 32 characters at most | `id is a-z, 0-9 and _, starts with a letter, 32 max` |
| Id | Unique across the questions | `id is used twice` |
| Question | Not empty, at most 500 characters | `the question is empty`, `500 characters max` |
| Choice options | 2 to 20 | `choice needs 2-20 options, has 1` |
| Score levels | 2 to 9 | `score needs 2-9 options, has 10` |
| Option or level | 1 to 64 characters each | `options are 1-64 characters` |
| Option or level | Unique within the question | `an option is listed twice` |
Options and levels are separated by commas, so a label cannot contain a comma. Short, plain, single-word labels such as `billing` or `furious` work best: a question whose labels the model cannot answer with comes back as `503 decision_unavailable`.
Some of these limits are the Playground's own. The API accepts longer ids and instructions, and more levels on a score question; see [Decision questions](/getting-started/decision-questions) for the API's rules.
### What the Playground does not build
The Playground sends only a state and questions. For these, write the request in code:
* `depends_on` and `ask_if`, to ask a question only when another answer calls for it. See [Conditional questions](/guides/conditional-questions).
* A shared `instructions` field for the whole run, `draws`, `think_tokens`, `question_order` and `deadline_ms`. See [Decision runs](/guides/decision-runs).
* Verdict runs against a JSON schema. See [Verdict runs](/guides/verdict-runs).
## Load an example
**Example requests** (meta `load into the editors`) holds five ready-made reads. Choose one to replace both editors with it and reset the answer panel. The first one is loaded when the page opens.
| Example | Questions |
| ------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| **Triage a support ticket** | 4: `urgent` (noul), `bucket` (choice over billing, technical, other), `tone` (score over calm, annoyed, furious), `churn` (noul) |
| **Is this license clause exclusive?** | 1 noul against a contract paragraph |
| **Route an inbound email** | 1 choice over five named queues: sales, billing, support, legal, spam |
| **Audit a page for SEO** | 4 questions on a JSON state describing a page: two nouls, a choice, a five-level score |
| **Screen a CV** | 3: `seniority` (choice), `rust_prod` (noul), `fit` (score) |
Each tag shows the question count and types, for example `4Q · noul choice score`.
## Run and read the answers
Press **Run**. While the read is in flight, **Decision** shows `Reading 4 questions in one pass` and an `elapsed mm:ss` counter. Nothing partial is shown: the answer arrives whole, or not at all. A read that takes longer than 30 seconds is stopped with `504 deadline_exceeded`.
Each **Run** sends a new request with a fresh idempotency key, so pressing it twice runs, and charges, two reads.
When the read answers, **Decision** shows `Neon 1.1` in its header and one card per question, in the order you wrote them.
| Type | The card shows |
| ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| noul | P(yes) as a large number such as `0.83`, and a bar from `0.00 no` to `yes 1.00`. There is no confidence for a noul: with two labels it would only restate the probability |
| choice | The chosen option, `confidence` (the probability on the chosen option), and a bar for every option with its probability, largest first |
| score | The score with two decimals, where it falls, such as `between annoyed (1) and furious (2), nearer furious`, each level numbered from `0` with its probability, and `confidence` |
Scores count from 0: on the legend `calm, annoyed, furious`, calm is 0 and furious is 2, and a score of `1.34` sits between annoyed and furious, nearer annoyed.
### This read
Under the answers, **This read** (meta `measured, not published`) describes the run.
| Row | What it shows |
| ------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `run_id` | The run's id, with **Copy**. Use it to find the run on [Usage](/console/usage) or read it back with `GET /v1/runs/{run_id}` |
| `model` | `Neon 1.1` |
| `questions` | How many questions were asked, with the number of draws and how the answer was read, for example `1 draw · slot constrained` |
| `cost` | What the read cost, in US dollars. Amounts under a cent show four decimals. The note says whether the figure was reported for the run or estimated from the price |
| `round trip` | Milliseconds from the console to the API and back, as the console measured it |
## Copy the request, or share it
**Request as sent** shows the exact HTTP request the Playground builds from your editors, with placeholders for the credential and idempotency key:
```http theme={"system"}
POST /v1/runs HTTP/1.1
Authorization: Bearer
Idempotency-Key:
Content-Type: application/json
{
"kind": "decision",
"model": "neon-latest",
"max_output_tokens": 64,
"state": "Everything is down and we have a demo at noon. ...",
"questions": {
"urgent": {"type": "noul", "instructions": "Does the customer need a reply within the hour?"},
"bucket": {"type": "choice", "instructions": "Which queue should this ticket land in?",
"criteria": {"billing": null, "technical": null, "other": null}},
"tone": {"type": "score", "instructions": "How annoyed does the writer sound?",
"criteria": ["calm", "annoyed", "furious"]}
}
}
```
Choice options go out as an object of option name to description, with no descriptions (`null`). Score levels go out as an ordered list.
**Copy as cURL** copies the same request as a `curl` command that reads your key from `$OPENTYPE_API_KEY` and makes a fresh idempotency key with `uuidgen`. Create a key on [API keys](/console/api-keys) first; the Playground itself runs with your console session and needs no key.
**Share** copies a link of the form `https://console.opentype.dev/playground#share=…`. Opening it loads the same state and questions into the editors of whoever opens it; it does not carry the answer, and it does not run anything. The state travels inside the link, encoded but not encrypted, so share it only with people who may read that text.
## Send the same read from code
This is the read above, sent with an API key that holds `runs_write`.
```bash cURL theme={"system"}
curl -sS https://api.opentype.dev/v1/runs \
-H "Authorization: Bearer $OPENTYPE_API_KEY" \
-H "Idempotency-Key: $(uuidgen)" \
-H "Content-Type: application/json" \
-d '{
"kind": "decision",
"model": "neon-latest",
"max_output_tokens": 64,
"state": "Everything is down and we have a demo at noon. This is the third outage this week and nobody has replied to my last two emails.",
"questions": {
"urgent": {"type": "noul", "instructions": "Does the customer need a reply within the hour?"},
"bucket": {"type": "choice", "instructions": "Which queue should this ticket land in?",
"criteria": {"billing": null, "technical": null, "other": null}},
"tone": {"type": "score", "instructions": "How annoyed does the writer sound?",
"criteria": ["calm", "annoyed", "furious"]}
}
}'
```
```ts TypeScript theme={"system"}
const res = await fetch("https://api.opentype.dev/v1/runs", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.OPENTYPE_API_KEY}`,
"Idempotency-Key": crypto.randomUUID(), // reuse the same value if you retry this request
"Content-Type": "application/json",
},
body: JSON.stringify({
kind: "decision",
model: "neon-latest",
max_output_tokens: 64,
state:
"Everything is down and we have a demo at noon. This is the third outage this week and nobody has replied to my last two emails.",
questions: {
urgent: { type: "noul", instructions: "Does the customer need a reply within the hour?" },
bucket: {
type: "choice",
instructions: "Which queue should this ticket land in?",
criteria: { billing: null, technical: null, other: null },
},
tone: { type: "score", instructions: "How annoyed does the writer sound?", criteria: ["calm", "annoyed", "furious"] },
},
}),
});
const run = await res.json();
if (!res.ok) throw new Error(`${run.error.code}: ${run.error.message}`);
console.log(run.decision.answers.urgent.probability, run.decision.answers.bucket.choice);
```
```python Python theme={"system"}
import os
import uuid
import requests
res = requests.post(
"https://api.opentype.dev/v1/runs",
headers={
"Authorization": f"Bearer {os.environ['OPENTYPE_API_KEY']}",
"Idempotency-Key": str(uuid.uuid4()), # reuse the same value if you retry this request
"Content-Type": "application/json",
},
json={
"kind": "decision",
"model": "neon-latest",
"max_output_tokens": 64,
"state": "Everything is down and we have a demo at noon. This is the third outage "
"this week and nobody has replied to my last two emails.",
"questions": {
"urgent": {"type": "noul", "instructions": "Does the customer need a reply within the hour?"},
"bucket": {
"type": "choice",
"instructions": "Which queue should this ticket land in?",
"criteria": {"billing": None, "technical": None, "other": None},
},
"tone": {
"type": "score",
"instructions": "How annoyed does the writer sound?",
"criteria": ["calm", "annoyed", "furious"],
},
},
},
timeout=60,
)
run = res.json()
res.raise_for_status()
print(run["decision"]["answers"]["urgent"]["probability"], run["decision"]["answers"]["bucket"]["choice"])
```
A completed read answers `200` with the whole answer set. The figures below are illustrative:
```json theme={"system"}
{
"run_id": "run_a4314b6cc08f4bd8814099a613abeb44",
"kind": "decision",
"state": "completed",
"input_digest": "2e7d2c03a9507ae265ecf5b5356885a53393a2029d241394997265a1a25aefc6",
"output_digest": "18ac3e7343f016890c510e93f935261169d9e3f565436429830faf0934f4f8e4",
"decision": {
"model": "neon-1.1",
"answers": {
"urgent": {"type": "noul", "probability": 0.97, "label_mass": 0.991, "answered_within_labels": true},
"bucket": {"type": "choice", "choice": "technical", "confidence": 0.81,
"probabilities": {"billing": 0.04, "technical": 0.81, "other": 0.15},
"label_mass": 0.964, "answered_within_labels": true},
"tone": {"type": "score", "score": 1.62, "confidence": 0.66,
"legend": {"0": "calm", "1": "annoyed", "2": "furious"},
"probabilities": {"0": 0.04, "1": 0.30, "2": 0.66},
"label_mass": 0.98, "answered_within_labels": true}
},
"draws": 1,
"read": "slot_constrained",
"stages": [["bucket", "tone", "urgent"]]
},
"usage": {"input_tokens": 180, "output_tokens": 9},
"cost_micros": 9,
"cost_basis": "provider_reported",
"replayed": false
}
```
Money in the API is integer micro-USD: `cost_micros: 9` is \$0.000009. See [Runs](/getting-started/runs) for every field.
## When a read is refused
A refusal replaces the answers with a dark panel: a heading, the HTTP status, the error `code`, its `message`, and the raw error body.
| Heading | Status and code | What it means | What to do |
| --------------------------- | -------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Refused before the read** | 400, usually `invalid_decision_questions` | The request broke a rule. The message *refused by the console before it was sent* means the Playground's own check caught it and nothing reached the API; any other message came from the API | Fix what the message names. See [invalid\_decision\_questions](/problems/invalid_decision_questions) |
| **Not enough credit** | 402 `insufficient_credits` | The balance does not cover the read. A read holds up to \$0.02 while it runs, so it needs at least that much to start | Choose the **Billing** link in the panel and add funds, or turn on auto-recharge. See [insufficient\_credits](/problems/insufficient_credits) |
| **Over the spend quota** | 429 `organization_spend_quota_exhausted` or `organization_token_quota_exhausted` | Your organization has reached its spend or token limit for this quota period | Choose the **Usage** link in the panel to see the period quota. It resets at the start of the next calendar month, UTC. See [Spend limits and quotas](/guides/spend-limits-and-quotas) |
| **Not allowed** | 403 `scope_denied` | Your role in this organization does not include `runs_write` | Ask an owner or admin of the organization. See [scope\_denied](/problems/scope_denied) |
| **No answer** | 413 `input_too_large` | The state is too long for the model | Shorten the state. See [input\_too\_large](/problems/input_too_large) |
| **No answer** | 503 `decision_unavailable` | The read could not be served, or the model could not answer with your labels | Run again. If it repeats with the same questions, make the labels shorter and plainer. See [decision\_unavailable](/problems/decision_unavailable) |
| **No answer** | 504 `deadline_exceeded` | The read did not finish within 30 seconds | Run again, or shorten the state. See [deadline\_exceeded](/problems/deadline_exceeded) |
| **No answer** | *the console server did not answer* | The console itself did not answer | Check your connection and run again |
If your console session has ended, **Run** takes you to **Sign in** with **Your session expired** instead of showing a refusal. Sign in again and rerun.
Every refusal from the API carries a `request_id`. Quote it, with the `run_id` if there is one, when you report a problem. See [Errors](/reference/errors).
## Related
* [Decision runs](/guides/decision-runs) - everything a decision request can carry, beyond what the Playground builds.
* [Decision questions](/getting-started/decision-questions) - noul, choice and score, their answers, and the API's limits.
* [API keys](/console/api-keys) - create the key that **Copy as cURL** expects in `$OPENTYPE_API_KEY`.
* [Usage](/console/usage) - find each Playground read, its tokens and its cost.
* [Models and pricing](/getting-started/models-and-pricing) - what Neon 1.1 costs per token, and how a read's cost is computed.